Open Policy Analysis for:
California Proposition 40, Analysis From Jaros and Rauh (JR)
1 The authors' own headline (Jaros and Rauh, NBER chapter c15504, Tax Policy and the Economy vol. 41, September 2026, PDF p.1): the average over their Monte Carlo draws, as printed from one seeded run (a run of the random draws started from a fixed seed number, so it gives the same draws every time). The explorer shows how far each input moves it, and the comparison overview sets it beside the BSZ analysis. The chapter revises the first version of the analysis, by Rauh, Jaros, Kearney, Doran and Cosso (Hoover Institution, SSRN 6340778, March 2026), which the pipeline also reproduces (footnote 2). This site calls the analysis JR, after the two authors of the version reproduced.
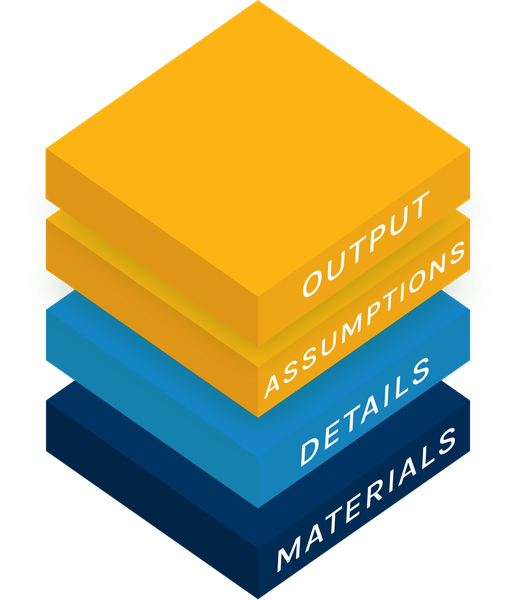
Three layers to understand the analysis
Explore the main estimate and its assumptions →
The mean net present value and the share of negative outcomes for every combination of the seven inputs of the authors' Monte Carlo: 2,187 combinations of three levels each, labelled data or guesswork. The page opens on the main estimate's setting. Each cell holds the exact expected NPV and the exact share of negative outcomes.
One reproduction, told two ways. Both read the same pipeline outputs.
The reproduction report →
The main estimate derived step by step, then the paper's sections in order (the revenue and its litigation discount, the income tax, the perpetuity, the break-even share, the Monte Carlo). Every number is read from the pipeline.
Slides →
A short deck, best on a laptop: the one equation, where each input comes from, why a perpetuity decides the sign, and what to argue about.
Materials for computational reproduction →
The R pipeline (built with {targets}, the R package that runs the pipeline's steps in order and records which outputs are current) and its Python twin, the test suite, every exported CSV, the source
manifest with SHA-256 hashes, and the nine mismatches between the authors' text, their
READMEs and their code. A guided summary is on the materials page, linked in the text below.
What the model says
The Act collects a wealth tax once; billionaires who leave stop paying California income tax for ever. The authors value that lost stream as a perpetuity (the same amount every year for ever, worth 1/r times the yearly amount today at discount rate r) and subtract it: NPV = revenue − (share of the income tax base that leaves) × (annual income tax) / (discount rate). They report the average NPV over 100,000 random draws of those inputs: the main estimate, −$38.9 billion (Jaros and Rauh, NBER, September 2026).1 Amounts are billions of dollars.
| NBER, Sept 2026 main estimate | |
|---|---|
| Mean NPV to the state, as printed | −38.9 |
| Share of outcomes below zero, as printed (85% in the text, p.1; 85.2% in the Figure 3 note, p.35) | 85.2% |
| Wealth tax revenue, the paper's revenue headline (p.1, p.23) | about 30 (28.4 to 35.6) |
| Mean NPV, authors' seeded run, reproduced | −38.89 |
| Mean NPV, exact expectation of the same draws | −38.98 |
| Mean revenue in the Monte Carlo's draw | 36.00 |
| Mean present value of income tax lost | 74.98 |
1 The authors' own headline (NBER PDF p.1). The comparison overview sets it beside the BSZ analysis.
Printed values from NBER PDF pp.1, 23 and 35. Three things the numbers show. First, the result is driven by the loss term: roughly 75 of present value lost against a few tens collected, because at the draws' 1.5% to 4.5% rates a dollar a year for ever is worth 22 to 67 dollars today. Second, the paper says the tax would collect about $30 billion (p.23: half of the base it recognizes after the pre-filing and Zuckerberg exclusions). The simulation behind the headline uses more: it draws revenue anywhere between 0 and 72, the most the tax could collect after the seven confirmed departures, with a mean of 36, the paper's litigation-discounted ceiling (0.5 × 72, its central revenue, p.33). So the headline rests on a revenue above the one the paper prints as collectible. Third, of the seven inputs that move the answer, six are guesswork; the explorer shows how far each one moves it. Whether the income tax loss really lasts for ever is the main point the BSZ analysis (Boll, Saez and Zucman) disputes.
What this OPA does not estimate. Both analyses, and so this OPA, take the measure as written (full text in docs/initiative/): the 5% rate, the 1 January 2026 residency date, the 31 December 2026 valuation date and payment in five yearly installments, with the wealth tax counted at its face value, not discounted over the five years. Neither analysis estimates the day-to-day movement of the Forbes base (GGSS, the Galle, Gamage, Saez and Shanske expert report written in support of the measure, note a range of $87 billion to $107 billion between January and July 2026, p.4 fn.8). The BSZ analysis alone adds the income tax from assets sold to pay the tax; the JR analysis alone weights the revenue by the chance the Act survives in court. Nothing is added to either here.
What reproduces
| Published result | Result |
|---|---|
| Baseline revenue, Sec 4.1 (pp.18-19) | 94.30 from the authors' workbook; the paper prints 94.20 (mismatch 6) |
| Revenue ceiling, Secs 4.1 and 4.3 (pp.19-21) | 100.91 at the valuation date (printed 100.9); 72.05 after the seven confirmed departures, printed 72.06 (mismatch 4) |
| Collectible revenue, Sec 4.4 (pp.22-23) | 29.57 (printed 29.6), range 28.40 to 35.59 |
| Pareto fit and Table 9, income tax (pp.26-30) | alpha 1.44; all 21 cells round to the printed digit, replaying the authors' random-number (RNG) stream |
| Table 10, break-even share (p.34) | all 3 cells match the printed digit |
| Monte Carlo, Sec 5.4 (p.35) | mean, median, SD (standard deviation) and share negative within Monte Carlo error |
"Match" means the reproduced value rounds to the printed digit for deterministic figures, and lies within four Monte Carlo standard errors for simulated ones. The test suite holds every comparison; the materials page gives its current count.2
Along the way we found nine mismatches between the authors' text, their READMEs and their code. Four of them concern this analysis.3 We reproduce the code as shipped and record each one:
- The code and eq. 18 call the 1.5% to 4.5% draw (r − g): r is the real discount rate and g the growth rate of the lost income tax. The sentence after eq. 19 divides by r alone (p.35), so one interval stands for two concepts.
- The revenue ceiling is 72 in the script, 72.06 in the README and in the paper's eq. 4 (p.22), and 72.05 in the person-level data.
- The litigation weight q = 0.50, the chance the Act survives in court: the code never multiplies by q; drawing revenue uniformly from 0 to 72 gives the same mean, 0.5 × 72, but a different distribution.
- The baseline revenue sums to 94.30 in the authors' workbook, and the grown person-level data give the same; the text prints 94.20 (p.19).
Full text, with file and line references: materials page.
2 The pipeline also reproduces the authors' first version (Rauh, Jaros, Kearney, Doran and Cosso, Hoover Institution, SSRN 6340778, March 2026). Its revenue chain, 94.30 / 67.51 / 55.10 / 45.59 from the authors' workbook, and all 18 and all 9 cells of its NPV and break-even tables match the printed digits. Its Monte Carlo's median and share negative match; the mean and SD do not quite (mismatch 9), and its printed mean equals the exact expectation, not the shipped seed's run.
- 1. Eq. 22 prints the revenue ceiling as 67.1; the code and the text use 67.51.
- 2. The text derives a growing perpetuity, C/(r − g) (p.18); the Monte Carlo divides by the plain rate.
- 7. Two memo cells in the workbook read from the wrong sheet (no headline number affected).
- 8. Table 9's central revenue, 42.0, is a typed literal with no derivation.
- 9. The Monte Carlo's printed mean and SD do not come out of the shipped seeded script.
How AI was used in this exercise, and what has been verified
The numbers on this page reproduce and are tested; what is still being completed is the author's own review of each part, recorded in the last column below, and the credit interview.
This work was a collaboration between the author and Claude Code (Opus and Sonnet models) across many sessions, not an AI working alone. The table records who led the work on each public object of the JR analysis, using the CRediT contributor roles. The answers come from a questionnaire the author fills in; they are not inferred from commit history. The table groups the 14 roles into three: ideas and direction (conceptualization, methodology, supervision, project administration), doing the work (data curation, formal analysis, investigation, software, validation, visualization) and writing (original draft, review and editing). Funding and resources do not apply. Each square in a cell is one role, coloured by who led it (key below the table). The last column is not part of CRediT. It records how closely the author has checked the object.
| Object | Ideas and direction | Doing the work | Writing | Human verification |
|---|---|---|---|---|
| Explorer Open Output | ||||
| Report Open Analysis | ||||
| Slides Open Analysis | ||||
| Repository Open Materials | ||||
| Overview page this page |
Not yet filled in as of October 2026. The record in credit/CREDIT.md (2026-10-01) carries the answers the author gave once, for the BSZ explorer, and asked to be applied to every object; the per-object interview for this analysis has not been run, so the table is left blank until it is.
Human verification uses three levels: not reviewed, lightly reviewed (checked, but the author cannot yet explain it clearly) and reviewed (the author can explain it to others). The automated test suites are mechanical checks, not an outside review. No other person has verified this work, and the original authors have not reviewed it.
25e84dd, and the source manifest lists each file
with its SHA-256 hash.