Open Policy Analysis for:
California Proposition 40, Analysis From Jaros and Rauh (JR)
This OPA site: AI generated, partially reviewed
The loss decides the sign. The income tax lost for ever is worth about $75B today, against $36B, the average wealth tax in the authors' simulation (their own estimate of what is collected is about $30B; what the model says).
1 Jaros and Rauh, NBER chapter c15504, Tax Policy and the Economy vol. 41, PDF p.1. The figure is the average of one seeded run of the authors' simulation (a run started from a fixed random number, so it gives the same draws every time). It revises a March 2026 first version by Rauh, Jaros, Kearney, Doran and Cosso (footnote 2).
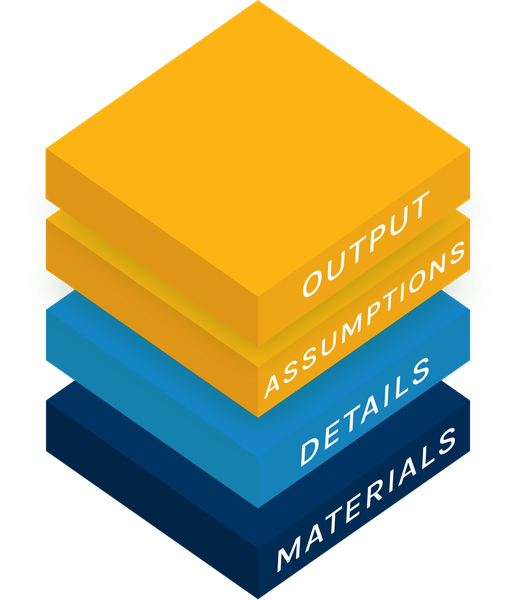
Three layers to understand the analysis
Explore the main estimate and its assumptions →
Move the five inputs of the authors' simulation, and two settings this OPA adds (an extra litigation weight and further growth), and watch the estimate and the share of negative outcomes change. It opens on the main estimate, and every combination is precomputed.
One reproduction, told two ways. Both read the same pipeline outputs.
The reproduction report →
The main estimate derived step by step, then the paper's sections in order (the revenue and its litigation discount, the income tax, the perpetuity, the break-even share, the Monte Carlo). Every number is read from the pipeline.
Slides →
A short deck, best on a laptop: the one equation, where each input comes from, why a perpetuity decides the sign, and what to argue about.
Materials for computational reproduction →
The R pipeline and its Python twin (the same computation written again in Python and checked against the R result), the tests, every exported CSV, the source files' hashes, and ten notes on where the authors' text, READMEs and code describe a step differently.
Guided summary: the materials page.
How AI was used in this exercise, and what has been verified #
The numbers on this page reproduce and are tested; what is still being completed is the author's own review of each part, recorded in the last column below.
This work was a collaboration between the author and Claude Code (Opus and Sonnet models) across many sessions, not an AI working alone. The table records who led the work on each public object of the JR analysis, using the CRediT contributor roles. The author gave these answers in a questionnaire on 2026-10-15, all 14 roles and the verification question for each object; they were not inferred from commit history. The table groups the 14 roles into three: ideas and direction (conceptualization, methodology, supervision, project administration), doing the work (data curation, formal analysis, investigation, software, validation, visualization) and writing (original draft, review and editing). Funding and resources do not apply. Each square in a cell is one role, coloured by who led it (key below the table). The last column is not part of CRediT. It records how closely the author has checked the object. The role-by-role answers are in CREDIT.md.
| Object | Ideas and direction | Doing the work | Writing | Human verification |
|---|---|---|---|---|
| Explorer Open Output | ||||
| Report Open Analysis | ||||
| Slides Open Analysis | ||||
| Repository Open Materials | ||||
| Overview page this page |
Human verification uses three levels: not reviewed, lightly reviewed (checked, but the author cannot yet explain it clearly) and reviewed (the author can explain it to others). The automated test suites are mechanical checks, not an outside review. No other person has verified this work, and the original authors have not reviewed it.
Claude Code agents also checked this OPA against every other set of assumptions the authors print. All four printed variations match. The author has not yet reviewed these checks.
25e84dd, and the source manifest lists each file
with its SHA-256 hash.
Difference between this OPA and the original analysis #
Everything of substance on this site belongs to the original analysis: Jaros and Rauh, The Net Present Value of the California Billionaire Tax Act, NBER chapter c15504 (Tax Policy and the Economy vol. 41, September 2026). The person-by-person base, the observed departures, the litigation weight, the perpetuity, the Monte Carlo and every conclusion drawn from them are the authors' work. This site adds no data and no new model.
The original analysis publishes all three layers. The chapter gives the output (a mean net present value of −$38.9 billion, p.1) and the details (its equations and their sources). The authors' public repository, github.com/bjaros20/wealth_tax (MIT licence), gives the materials: workbooks, R scripts and person-level data. What a reader cannot easily see is how the three line up. The code reproduces the published results of both versions. In ten places the text, the READMEs and the code describe the same step in different words or numbers, five of them in the September version. None changes a printed result (see the materials page).
So the difference is not in what is claimed but in what can be checked. This OPA rebuilds the analysis in R, with a Python twin and a test suite. It runs the authors' code as shipped and records each of those notes rather than fixing it. Beside the printed −$38.9 billion from one seeded run, it computes the exact expectation of the same draws, −$38.98 billion, a number that does not depend on the seed. It labels each input as data or guesswork. Where this site and the chapter disagree, both numbers are shown, and the chapter is the reference.
What the model says #
The Act collects a wealth tax once; billionaires who leave stop paying California income tax for ever. To put a loss that lasts for ever, and grows each year, into today's dollars, the authors divide this year's loss by a small rate: the interest rate minus the loss's yearly growth, r − g. Each run of their model picks that rate between 1.5% and 4.5%. The low end is the S&P 500 dividend yield, their measure of r − g (PDF pp.31-32). They subtract that loss from the revenue: NPV = revenue − (share of the income tax base that leaves) × (annual income tax) / (r − g). They report the average NPV over 100,000 random draws of those inputs: the main estimate, −$38.9 billion (Jaros and Rauh, NBER, September 2026).1 Amounts are billions of dollars.
| NBER, Sept 2026 main estimate | |
|---|---|
| Mean NPV to the state, as printed | −38.9 |
| Share of outcomes below zero, as printed (85% in the text, p.1; 85.2% in the Figure 3 note, p.35) | 85.2% |
| Wealth tax revenue, the paper's revenue headline (p.1, p.23) | about 30 (28.4 to 35.6) |
| Mean NPV, authors' seeded run, reproduced | −38.89 |
| Mean NPV, exact expectation of the same draws | −38.98 |
| Mean revenue in the Monte Carlo's draw | 36.00 |
| Mean present value of income tax lost | 74.98 |
The authors report the share below zero as the share of plausible parameter combinations with a negative net present value (PDF p.35). Their draws are independent and uniform over ranges that are themselves guesswork, so the share is not a probability that the tax loses money: it moves with those ranges, as the explorer's Rate 1.5% and Rate 4.5% settings show.
Printed values are from NBER PDF pp.1, 23 and 35. The numbers show three things. First, the result is driven by the loss term: roughly 75 of present value lost against 36 collected. At the draws' 1.5% to 4.5% values of r − g, a dollar a year for ever, growing, is worth 22 to 67 dollars today.
Second, the paper says the tax would collect about $30 billion (p.23). The simulation behind the headline draws revenue anywhere from 0 to 72, the most left after the seven publicly reported moves (the chapter's "publicly confirmed pre-snapshot departures", PDF p.21). That draw averages 36 (0.5 × 72, p.33), above the 30 the paper calls collectible. The chapter uses 36 as its central revenue in the break-even analysis (p.33) and treats both 72 and 30 as upper bounds that assume no undocumented departures (p.24).
Third, of the five inputs of the authors' simulation, four are guesswork, and the explorer adds two settings of its own. The explorer shows how far each one moves the estimate. The authors assume leavers do not come back, because the Act permanently lifts the constitutional cap on taxes on intangible property and lets the Legislature change the Act by a two-thirds vote (chapter PDF p.32). Whether the income tax loss lasts for ever is the main point the BSZ analysis (Boll, Saez and Zucman) disputes.
What this OPA does not estimate. Both analyses take the measure as written (docs/initiative/), with the wealth tax at face value. Neither counts the deferral charge of 7.5% a year that the Act adds to installment payments. Only the JR analysis projects the base to the 31 December 2026 valuation date. It grows the 2025 list by 7%, the yearly growth of billionaire wealth that the Act's own findings state, and checks the result against a forecast from past growth (chapter PDF pp.12-13). The BSZ analysis uses the 1 July 2026 list (BSZ's website tracks the estimate day by day, PDF p.23). The BSZ analysis alone counts the income tax from asset sales and the non-US-citizen residents. The JR analysis alone weights the revenue by the chance the Act survives in court.
What reproduces #
| Published result | Result |
|---|---|
| Baseline revenue, Sec 4.1 (pp.18-19) | Reproduces. The paper prints 94.20, a value typed into the authors' workbook, and every later number built on it reproduces; the workbook's own sum is 94.30, 0.1% higher (note 6) |
| Revenue ceiling, Secs 4.1 and 4.3 (pp.19-21) | 100.91 at the valuation date (printed 100.9); 72.05 after the seven publicly reported moves, printed 72.06, the difference of the two figures rounded first. The script and the chapter's later pages use 72 (note 4) |
| Collectible revenue, Sec 4.4 (pp.22-23) | 29.57 (printed 29.6), range 28.40 to 35.59 |
| Pareto fit (a line fitted to the counts of top earners by income, used to estimate what the top earners make) and Table 9, income tax (pp.26-30) | alpha 1.44; all 21 cells round to the printed digit, replaying the authors' random draws |
| Table 10, break-even share (p.34) | all 3 cells match the printed digit |
| Monte Carlo, Sec 5.4 (p.35) | the seeded run gives the authors' 100,000 draws exactly; its mean, median, SD (standard deviation), 5th and 95th percentiles and share negative each round to the printed digit |
| Net present value under other assumptions (first version, p.20 and Table 9) | All 4 printed variations match; the September chapter prints none. A 2% tax rate case in the authors' repository cannot be set here. The checks |
| Other numbers the papers print | Of ten, nine reproduce: seven at the printed digit, and two once the paper's rounding (the semi-elasticity of 5.73, the percentage of the tax base lost per percentage point of tax, uses the round 72) and seed are allowed for. One does not quite: Table 8's "expanded departures" (about 42% of the base) gives a semi-elasticity of 8.35 from the authors' records against the printed 8.41. It is not an input to any estimate. The checks |
"Match" and "reproduces" mean the reproduced value rounds to the printed digit, or differs only because the paper rounded or typed an intermediate figure (0.1% or less), for deterministic figures; and lies within four Monte Carlo standard errors for simulated ones, since two runs with different seeds never agree exactly. The test suite holds each of these comparisons, the SD included. The materials page gives its current count.2
Along the way this OPA kept ten notes on where the authors' text, their READMEs and their code describe the same step differently. None is a failure to reproduce a printed result. Three are rounded or typed inputs, one is seed variation and six are documentation notes. Five concern the September chapter. The other five concern only the March first version.3 This OPA reproduces the code as shipped and records each one:
- Documentation. The chapter's draw is r − g, the interest rate minus the lost income tax's yearly growth (a real rate): eq. 18, the code and the NBER README all say so. One sentence after eq. 19 writes C/r instead (p.35).
- Rounding. The revenue ceiling is 72 in the script and on the chapter's later pages (pp.24, 33), 72.06 in the README and in eq. 4 (p.22), and 72.05 in the person-level data: one value at three roundings.
- Documentation. The paper sets the litigation weight q, the chance the Act survives in court, at 0.50. The code never multiplies by q. Its revenue draw from 0 to 72 has the same mean, 0.5 × 72, but a different spread.
- Typed input. The baseline revenue sums to 94.30 in the authors' workbook, and the grown person-level data give the same. The text prints 94.20 (p.19), a value typed into the workbook, and every later number built on it reproduces.
- Documentation. The text prints one formula, the top 212's share of bracket tax, as 39.0% (p.27) and as 38.8% (p.28). The code gives 38.85%, and 34.75% before it rescales the schedule.
Full text, with file and line references: materials page.
2 The pipeline also reproduces the authors' first version (Rauh, Jaros, Kearney, Doran and Cosso, Hoover Institution, SSRN 6340778, March 2026). Its revenue chain, 94.30 / 67.51 / 55.10 / 45.59 from the authors' workbook, and all 18 and all 9 cells of its NPV and break-even tables match the printed digits. Its Monte Carlo summary reproduces within Monte Carlo error. The printed mean and SD equal the model's exact mean and SD at the printed digit; the shipped seed's run differs slightly, which is seed variation (note 9).
- 1. Documentation. Eq. 22 prints the revenue ceiling as 67.1; the code and the text use 67.51.
- 2. Documentation. The text derives a growing perpetuity, C/(r − g) (p.18); the Monte Carlo divides by the plain rate.
- 7. Documentation. Two memo cells in the workbook read from the wrong sheet (no headline number affected).
- 8. Typed input. Table 9's central revenue, 42.0, is a typed literal with no derivation; the table reproduces with it.
- 9. Seed variation. The Monte Carlo's printed summary comes from another run of the same code; it is within Monte Carlo error of the shipped seed's run.